Introduction About Site Map

XML
RSS 2 Feed RSS 2 Feed
Navigation

Main Page | Blog Index

Archive for the ‘Browsers’ Category

Web Applications Without JavaScript

Horde

Web-based calendar in the Open Source Horde project

ONE of the more ingenious technologies around involves user interfaces that are embedded in Web pages. Taking full advantage of powerful, modern Web browsers, it is possible to build fully-blown applications that are operable from merely any platform. One of the latest packages as such achieves all of this without any JavaScript. Have a look at the project summary.

ZK is an open-source Ajax Web framework that enables rich UI for Web applications with no JavaScript and little programming. With event-driven feature-rich components, developing becomes as simple as programming desktops. With a markup language, designing becomes as simple as authoring HTML.

Cutting-Edge CSS

The Web Developer extension in action

CSS analysis with The Web Developer extension (click to enlarge)

STUART Nicholls has been doing some stunning work on cutting-edge cascading style sheets (CSS). I first noticed his work roughly one year ago. More latterly I came to discover that he had implemented pure-CSS fonts! Imagine the complexity. Have a look at some time-consuming illustrations of the power of CSS:
No images are involved in creating any of the above, among many more which you can find in the site.

Also see: Barcharts using CSS

Slashdot CSS Contest

Slashdot on April 1st
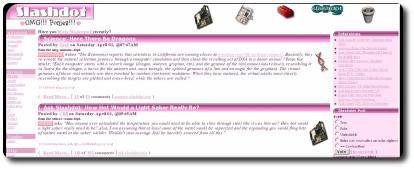
The front page of Slashdot on April 1st, 2006

AFTER Slashdot’s transition to proper CSS-based layout (it used to be heavily based on tables), a contest is run to select the new, permanent site design. Here are some of the latest design contenders. Some of these designs are included as actual Web pages, whereas others are appended as PNG-formatted screenshots. Shown above is the Slashdot front page as of April 1st this year.

History and Bookmark Search

Firefox in the dock

HAVE you ever thought of an (electronic) article that you once saw or read? Could you find it easily after a few weeks, months, or years? How about if you bookmarked it? Would it always allow the article to be found again? And if so, how quickly can it be found?
Mozilla Firefox offers some good facilities for previously-browsed pages to be found. Both History and Bookmarks in Firefox have a ‘find as you type’ widget. However, this only contains and uses page titles.

What would make a better feature that is able to perform a more fuzzy and full-body search? The first option is to permit a search engine to spy on you and retain a record of pages that you follow. In turn, it will index these in isolation and allow your pages of choice to be searched cohesively. It is as though the knowledge conveyed in the index partly corresponds to what you already know. So, it is somewhat of a brain search, which makes the assumption that you carefully read every Web page you visited.

The option which exposes the user to a lesser privacy invasions is this: allow the Web browser to index a page whenever one is visited or only once at the end of the day. The index is of course cumulative and it permits the user to search just a ‘subnet’ — that which he/she has already explored.

Google’s Perception of rel=’nofollow’

Iron links

Links can lose their value and
get rusty, even with Google

I was innocently browsing the Internet this morning. By serendipity, I then arrived at a page where Google boast their contributions to Open Source software through funding (Summer of Code). It is only one example among others. But then, upon immediate inspection, merely all links turned out to be rel="nofollow"ed. SearchStatus made it evident by highlighting those links with red shades.

I have always adamantly believed that the purpose of this new class for links was different. I thought it was introduced in order to prevent and deter spam, among other things such as accommodation for microsformats (e.g. XFN). Here is the snag: If Google themselves are using rel="nofollow" to obstruct dynamicity into relevant, on-topic links, why should anyone else be hesitant to do so? rel="nofollow", a concept that was put in place by Google, is confirmed to have become something that can be misused. Its use has gone beyond the so-called ‘link condom’ (for spam) utility. Otherwise, Google demonstrate hypocrisy herein.

Preview Thumbnails in Search Engine Results

Preview in thumbnail
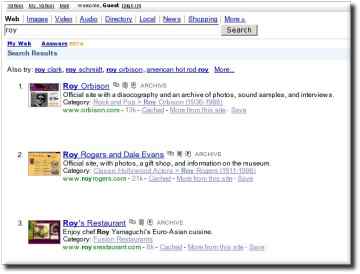
Yahoo search results for “roy” with
thumbnails (previews) added ‘on the fly’

LAST year (July 2005 to be precise), I conceived a hypermedia system/Web browser wherein page previews get put adjacent to incoming/outgoing links. Such previews should serve as somewhat of a screenshot that rids the need to explore deeper. They give the surfer a shallow preview, making arrival at pages more rhetoric or unneeded. The surfer can become selective based on the appearance of the destination page.

Screenshot-type extensions turn out to exist in Opera and even in Mozilla Firefox. In fact, there are several such extensions for Firefox. One of these extensions is BetterSearch, which manipulates search engine results pages directly. Thumbnail zooming is possible too and thumbnails rely on Alexa’s thumbnails database with the caveat that only front pages are displayed, rather than the actual pages delivered to the SERP. In BetterSearch, almost a dozen search engines are supported. One has to remember and constantly bear in mind that a fast connection is required for pragmatic use. It can otherwise become an obstruction — a time-consuming obstacle

Browser Racism

Firefox in the dock
I choose Firefox primarily because of its
extensions. Some site continue to snub it.

BROWSER discrimination, as it is frequently referred to, is always a bad idea. Sadly, many sites still use deprecated JavaScript code to distinguish between Netscape and Internet Explorer. In reality, most of today’s Web sites can be rendered almost ‘pixel perfect’ by Camino, Safari, Mozilla, Opera, Netscape, Firefox, Internet Explorer and several more obscure Web browsers, even Konqueror.

Vis-a-vis Konqueror, functionality in Konqueror is being extended all the time and its renderer (KHTML) improves rather quickly too. It no longer plays catch-up, but the acceptance of new browser is hindered by vain user-agent sniffing, which in itself is a terrible practice. In the case where proxies are being used, the assumptions might be wrong. In other circumstances, this promotes agent forging/spoofing, which only adds noise to Web statistics, adds bloat the applications and makes an unhealthy industrial environment for all to compete in.

Retrieval statistics: 21 queries taking a total of 0.077 seconds • Please report low bandwidth using the feedback form
Original styles created by Ian Main (all acknowledgements) • PHP scripts and styles later modified by Roy Schestowitz • Help yourself to a GPL'd copy
|— Proudly powered by W o r d P r e s s — based on a heavily-hacked version 1.2.1 (Mingus) installation —|