Introduction About Site Map

XML
RSS 2 Feed RSS 2 Feed
Navigation

Main Page | Blog Index

Archive for the ‘Research’ Category

IPMI 2005

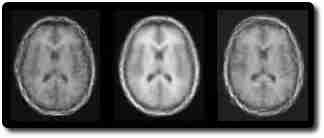
Poor appearance model
An example of a poor appearance model of the brain

IPMI, an international conference on medical imaging, has come to its end. Worth pointing out is the fact that our presentation was delivered first among hundreds in this conference, which began last Monday. I am not the first author; Carole Twining is.

If you take interest in my research, have a look at project MARS, AART or the comprehensive research index. I also maintain the Computer Vision Digest, which is much broader in terms of scope.

Playlist Similarity

Vinyl record

How does one identify music which has potential of being liked? Music, unlike textbooks, does not contain text or keywords. Its tags are not always valuable either. An interesting paper from Trinity College Dublin describes a method by which music adapts to the preferences of listeners (PDF). However, can this be done purely based on prior data? Data that is provided in advance unlike in real-time? A List of records maybe? Playlists perhaps? We seem to be coming closer to realisation of this idea.

Image similarity measures are one focus point of my research; also sparks to mind is Google’s notion of ‘Similar Pages’. Why not apply similar principles to music? I now collect big daily dumps of music that I listen to (output to files using the following technique ). Bound to each entry is the time when a track started. From this, one can infer which tracks are being skipped. Alternatively, full, raw playlists can be of use and might, in fact, be more manageable as well. By exploiting a large collection of playlists, the nature of the genres can be better understood.

Given all of this data, it can potentially be used for collabortive playlist sharing, somewhat like del.icio.us (see previous reference to del.icio.us with a gentle introduction). Users can then discover other songs they might like based on other people’s playlists. The more data, the more accurate statistics will be. Getting large lumps of input (playlists) is effortless too. Just imagine yourself the scenario:

You can automatically find playlists most similar to yours and recognise the most-played tracks on that playlist. Social software has seen great success recently, so exchange of music preferences and recommendations is probably the way to proceed.

My new Project: MARS

MARS logo
“That MR brain image in the background is mine… but don’t tell anybody…”

I am taking on a new project these days. Its name comprises the words Models of Appearance, Registration and Segementation. It may prevent me from posting items in the Web log and in the newsgroups. If you wish to have a look at research work that I currently do towards my Ph.D., have a look at the new site, which I have arranged using the almighty PHP-Nuke.

3D City Maps

There has recently been some gossip about Google’s project which involves 3D maps of San Francisco, as well as other cities. More details have been disclosed today (Kudos to Slashdot) including some pictures and related research papers (PDF).

3D map
An example of output maps, which can be generated by trucks with laser tracers

MATLAB Pinnacle

Pause/Resume Demo

Statistics for the month of April have just come out from MATLAB Central. I was ranked 1st world-wide, jointly with Luigi Rosa.

I am nearing 20,000 downloads and this figure should be exceeded later this month. It is rewarding to know that many programs out there have my DNA.

Computers Learn Vision

It has been exactly one month since I started taking 20 photos a day. Although this commitment barely maintains an element of joy, it persists and I would love to see how far it can go. Why am I collecting all of this data? Being in the field of computer vision (my daytime occupation), I estimate that within a few decades we will be able to index visual data and extract rich information from it, including information about one’s daily life.

A computer will have a reliable understanding of image contents — understanding that surpasses the human eye and mind. Want a photo that which a Labrador drinking water from a fountain on a sunny day? Want a descriptive verbal interpretation of a given distorted image? This will probably be practical in the distant future. It is a machine learning/pattern recognition task taken to extremity.

Maths Tower
The Maths Tower on campus (undergoing demolition)

Evaluating Models and Registration

I am going to present recent research work at UCL tomorrow. Bound to this presentation are some graphics files (with captions). Older, unused slides are available to anyone who is curious. I will most likely modify text on the train and upload the changes during the weekend.

MIAS IRC presentation

Retrieval statistics: 21 queries taking a total of 0.102 seconds • Please report low bandwidth using the feedback form
Original styles created by Ian Main (all acknowledgements) • PHP scripts and styles later modified by Roy Schestowitz • Help yourself to a GPL'd copy
|— Proudly powered by W o r d P r e s s — based on a heavily-hacked version 1.2.1 (Mingus) installation —|