Search Engines and Benchmark Subjectivity
 Filed under:
 EARCHING of the Web is no exact science. If it was, its exhaustive exploration would be infeasible. The more formidable search engines amass information from million of Web sites, each containing huge lumps of information — both textual and media. That information, in turn, could be interpreted and/or indexed in a variety of different forms. Rarely is the content truly understood, which is my personal motivating for knowledge engines.
Mathematics and physics could be argued to be inexact sciences as well, at least when a variety of man-made, non-fundamental fields are introduced. Think of computer science, for example. Its fundamentals assimilate to this complex problem, which is searching the World Wide Web. It is associated with ad-hoc solutions. Computational theories which relate to Turing machines are not tractable enough to make a most correct and efficient algorithm ever crop up and stand out.
Don Knuth has written his popular series of books on the issues of correctness and efficiency in common algorithms. It proves an elegant reference to many computer science practitioners. Problems which are simple, such as element or number sorting, are still handled differently by different algorithms and their efficiency is dependent upon the architecture involved, the scale of the problem, and its nature. Search algorithms likewise, which is why they should be engineered differently depending on a number of key factors. Hence, judgement of the quality of search engines cannot be done objectively, but only ever be estimated using test cases and artificial scoring schemes.
 Still, everyone wants to discover the perfect recipe to outperforming Google. Others try to reverse-engineer their algorithms and cheat (fame and riches owing to ‘Google juice‘ that is channelled to one’s site/s). Many of us continue favour and recommend Google, which brings the largest number of referrals to most sites in existence. There is a danger here though. Large search engines are the main target for deceit and they are easily confused by spam inasmuch as they are inclined to pick up rare and valuable content.
Quality of search is probably in the mind of the searcher and the result of hearsay — somewhat of a ‘cattle effect’. Even engines that spit out cruft might be defended unconditionally by their innocent users. This may lead the competition to forfeiting the battle and invest fewer resources (e.g. datacentres) in the attempt to catch up. Phrases like “Google it” do not help either as they promote a search monoculture at best.
Related item: Search Engines and Biased Results


 ERELY everyone has come across corrective discrimination wherein gender/race quotas are specified, and in turn promote diversity. We should be taking similar principles to diversify computing. This would be an intersting experiment, from which all would benefit. The move has an increasingly-justified place in the avoidance of

 CCASIONALLY I feel like as though we are witness to an ethical corruption. There is a thriving industry out there that takes advantage of people being drunk or stranded. In other circumstances, social weaknesses are to be blamed, in what can only be described as ‘cattle effect. I’ll present a couple of examples.
 HIS short essay describes a variety of ways which I have found to increase ‘desktop productivity’. It identifies and covers 3 aspects of customisation, albeit without much obvious connection. Think of them as streams of consciousness.
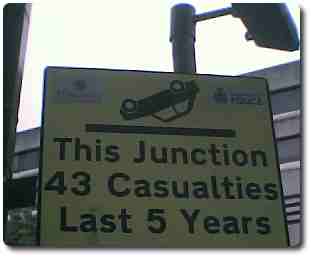
 RIVING can be a time-occupying and risky errand, which under certain circumstances is unavoidable. I got my license at the legal age (which was 17) and have not been involved in any accidents.