Introduction About Site Map

XML
RSS 2 Feed RSS 2 Feed
Navigation

Main Page | Blog Index

Archive for the ‘Internet’ Category

Screenshots on links

Imagine yourself the following scenario:

You open a page filled with links and adjacent to each individual link is a little visual page preview generated on-the-fly — a pseudo-screenshot if you like.

Ever since the inclusion of tabs in major browsers, navigation of several destinations at once (forking) has been possible. Nonetheless, under normal curcumstances, only one page could be viewed at any given point in time. Several previews, much like thumbnails of imagery, can increase productivity significantly. Allow me to illustrate this graphically.
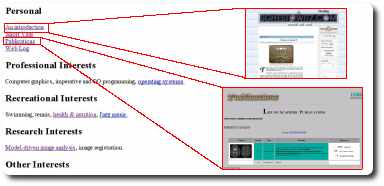
Previews
In this text-only page, on-line preview
of destination pages would help greatly

To make such extended hypertext protocol viable, bandwidth barriers must be breached. Every link in any given page (with a possible threshold on the number of previews) will result in site hits. This inconsistent and unfamiliar behaviour has implications on server load, statistics and even CPU load which is required page rendering. Perhaps one can argue that RSS feeds have had a similar impact.

Dangers of Naming

Saloon
Will mentioning of the name be good for business?

There is a fun and yet scary thing about maintaining sites which hold good search engine ranks. The mentioning of names (names of places, but of individual people in particular) ‘invites’ visits by the ‘owner’ of that name or its friends, associates, and clients.

If the person in question is technology-savvy, it should not take more than a day for him/her to locate the source. So-called hat tips make the approach even easier (intentionally so) and services like Technorati assist the process as well. To those who approach the computer only on occasions it can take weeks or months to find out what others have said about them. This perhaps would finally occur when ego surfing (searching names that relate to self).

This power can be exploited or misused, but most importantly, it is something a webmaster must always be aware of.

Remote Data

Server room
Will you trust these for storing your mail?

Much information is migrating from our hard-drives to on-line servers: files (e.g. FTP), bookmarks (Deli.ci.us or portals), (Web-based) mail, feeds (analysis and statistics by Feedburner), photos (notably Flickr) and newsgroups (e.g. Google Groups) are merely a few more major examples.

Storage of personal data remotely has its powers:

  • Data can be accessed from anywhere regardless of the computer used
  • Backup is often handled by the service providers
  • Liability shifts to service providers
  • Inferences, e.g. spam filtering in GMail that adapts in accordance to users’ purging behaviour, social bookmarks, tagging…

Some people, myself included, have learned the hard way why the dependency upon third parties is risky. Hard-core users have their todo lists on-line, their mail on third-party servers and often files or address books stored remotely. The dangers:

  • On-line servers may disappear due to bankruptcy, takeovers or corruption
  • Import (and especially export) facilities are intentionally limited to suppress user mobility
  • Servers fail or periodically go down; timescale for recovery is unknown
  • Limited space and ‘premium’ packages that later emerge
  • Pricing and policies which change, e.g. Yahoo stopped free POP3 support around 2001 (I too was a victim)

It is easier to blame somebody else but yourself as in the case of third-party dependencies. Yet, things are different when you control your own — shall we say — destiny. Ownership of your own domain is the first step towards an easier life in which the system administrator is yourself.

Internet Plagiarism

Sky scrapers
Scrapers: which is the original and which is the fake?

There has recently been a rise in the number of scrapers across the Internet. Such sites ‘scrape’ content off other existing, content-rich sites and put it along with ads on the Internet. They can make a ‘quick buck’ by attracting errant users who use search engines. In the process, genuine sites lose visitors and potentially get penalised for duplicate content.

Apart from illegal scrapers and spam, there are marginal cases of plagiarism. Imported content must always be:

  • Contained within quotes
  • Quoted in part so that it contains enough text to serve as a ‘teaser’ for the original information source
  • Include at least one prominent link to the source

Google Earth

Google Earth
Click to enlarge the image

Google Earth is a project which strongly impresses me. I got hold of a Windows machine where Google Earth had been installed and grabbed a few screenshots of streets around Manchester, UK.

Given the satellite data, this technology is not overly innovative. All that is required are mappings of existing satellite images onto a sphere, then relying on OpenGL acceleration. The real issues to be faced are bandwidth and Google’s progress on 3-D geographical data acquisition.

What screenshots cannot show is the excellent real-time interaction with the scene. Roads, street names and other details can be toggled on/off. There is also some highly continuous motion when hovering from one place to another. To get a better impression, you may wish to view this gallery with more sample images.

Registering a Domain

When I first registered schestowitz.com, I registered it for 10 years — until 2014 — that is. At the time, I could not imagine that search engines would favour sites that are committed to a long-term future. But guess what? It turns out they do.

Paying your host for domain renewal annually is a poorer choice; furthermore, it is undesirable if your site has real potential. As unfair as it may seem, Google definitely favour sites which are registered for many years and will position these higher in the SERP‘s. This helps in identifying sites that are serious about their vocation and might rule out spam sites or scrapers (site that steal content for fast, artificial growth).

There are important factors when selecting a domain name, which is a very influential choice. A domain name needs to be:

  • Short
  • Memorable (to distinguish from “short”. For example, m3d4n8sm.com versus feedsync.com)
  • Decent and trustworthy

If you struggle to think of a good name that is also available, have a quick look at the enormous list of deleted (i.e. registered, then neglected) domains in the ICANN-inclined whois.net.

Changing of a domain is far more problematic than people imagine. Change of bookmarks, loss of SE ranks, update of links (where still possible) and loss of identity are all involved in such transition. A domain change can be a bitter, cruel and highly effort-consuming process, which makes the initial choice of a name very crucial.

schestowitz.com
schestowitz.com: rising from ~20 to ~1,000 daily visits in less than one year

Syndicating Static Pages

Computer shell
Getting just the valuable data from pages

Feeds have definitely revolutionised the way we use the Internet. We can efficiently seek and exploit content without having to undertake laborious navigations in sites. The content is delivered to the user so there is no need to actively obtain it or ever spend time re-reading segments of text.

I have just finished brushing up the script I developed for syndicating static pages that do not offer feeds. Windows users can use it under Cygwin; Mac and Linux user can use it at much great ease. All details and code are contained in the more comprehensive page.

Retrieval statistics: 21 queries taking a total of 0.090 seconds • Please report low bandwidth using the feedback form
Original styles created by Ian Main (all acknowledgements) • PHP scripts and styles later modified by Roy Schestowitz • Help yourself to a GPL'd copy
|— Proudly powered by W o r d P r e s s — based on a heavily-hacked version 1.2.1 (Mingus) installation —|