Introduction About Site Map

XML
RSS 2 Feed RSS 2 Feed
Navigation

Main Page | Blog Index

Sunday, February 19th, 2006, 6:53 am

Code Optimisation and Miniature Web Servers

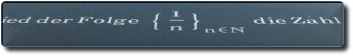
Equation

IN programming, efficiency always entails a cost. Contrariwise, simplified and inefficient code is often easier to understand. Where can balance be found? Can it ever be found? Efficiency is often preferred by so-called ‘power users’, whereas others opt for simplicity. Consequently, when negotiating projects, either at code-level or when deciding on UI design, flame wars may arise among developers or avid users.

Let us consider code optimisation. If the programmer wants to go all the way, (s)he could optimise by shortening variables, removing excessive spaces, and stripping out newlines. In such circumstances, interpreted code will be quicker, albeit less meaningful when an error arises and goes verbose. This is nothing like bytecodes and JIT, but similar rules should apply.

Good code should be well-structured, easily-readable, elegant, and well-documented. If the code is compiled, all comments should definitely stay in tact rather than ever be stripped. Automatic documentation can fit nicely in the source rather than be generated and made peripherally available, e.g. via Web pages. The only exception is debugging ‘bits’, which could definitely slow down program execution. As long as the developer keeps the original and saturated version of the code public, however, nobody need get entangled in closed-source traps.

On to an exciting prediction, with lowered file sizes and optimised code, programs could scale better on Wi-Fi-driven Web servers which run on a PDA in one’s pocket. Such server must be properly taken good care of, as well as the Internet connection, which is as vital as that of a synapse. With the growth of smaller devices, the need for efficiency is better realised.

Saturday, February 18th, 2006, 2:47 pm

The Goobunto Myth

Google on a computer screen

After previous denial by Google as regards the release Ubuntu Linux variants, comes yet another clarification.

Google very likely is using the Ubuntu version of Linux internally, but Ubuntu project founder Mark Shuttleworth said this week he doubts the Internet search giant plans to turn it into a product.

“As far as I’m aware there is absolutely no truth to the rumor that Google plans to distribute a derivative of Ubuntu as a Google OS,” Shuttlworth said on his blog. “As exciting as that may be for Linux, it wouldn’t make sense for Google, and so far they’ve been pretty sensible about their projects.”

“The ‘goobuntu’ you may have heard of is just a modified version of Ubuntu,” he said. “Technically, there’s likely to be a ‘goobian’ and a ‘goohat,’ too,” referring to Linux versions from Debian and Red Hat.

Perhaps it is a shame, given Google’s personnel, skills, and budgets. Then again, no further commercialisation and privatisation of Linux is probably a positive thing.

Items on Goobuntu: Google Controversies, Google: Primary Rumours Victim

Saturday, February 18th, 2006, 5:12 am

Musing De Jour: Telephone vs. Keyboard

Shortcut keysDigits on a telephone’s keypad and keyboard arrangements of numbers (the right-hand-side of standard keyboards) are inconsistent in terms of layout. Have you ever wondered why? I sure has to stop and ponder myself . I tried to flip the telephone upside down to achieve consistency, to no avail. The zero ends up at the wrong end (top) and the whole ‘image’ is reversed; “mirrored”, to be precise.
Isn’t such layout supposed to be standardised for the user’s sake? It definitely simplifies habits and make keypresses more instinctive. There must be some historical motives. The pulse phone and the dial probably predate computer keyboards. In other words, tone dialling with the modern one-stroke input came after computers, so could possibly inherit the same, perfectly-acceptable layout.

Most of us can switch easily between the two layouts. Many use both the phone and the ‘NumLock setting’ on for numerical data entry (highly popular among accountants). I hear that the same arguments apply to alternative layouts of characters, e.g. Dvorak keyboard layout, which need not necessarily interfere with QWERTY habits. QWERTY is an arbitrary scheme, which if I recall correctly was only justifiable as it avoided mechanical collisions in typewriters. It is not optimised for quick input, however, and it almost neglects entirely the frequency of keys being pressed. On the other hand, one must consider the issue of universality since not all languages use a given character at similar frequencies. it all boils down to the question: is greater (keyboard) diversity a positive thing?

Friday, February 17th, 2006, 2:11 am

On the State of Platform Security

Bill Gates

SANY items on security were published last night. Perhaps the most prominent among these was the mentioning of a possible Mac OSX vulnerability (more details here). On yet another front, a ‘bounty hunt’ for Windows critical flaws has begun. Last but not least, Red Hat further beef up Linux desktop security.
Linux appears to be the least notable victim of vulnerabilities, despite the prevalence of Linux (and UNIX derivatives or variants) servers. A survey confirms this while debunking Microsoft’s deceiving, self-funded campaigns, which try to convince people otherwise. With that in mind, Korea plans Linux city and Novell is preparing for the big Linux adoption wave.

Previous items on Windows security (or lack thereof):

On Mac security: the BBC article which begged for an outcry.

Technology commentator Bill Thompson is worried about the lack of herd immunity among his fellow Apple Mac users.

Thursday, February 16th, 2006, 3:56 pm

Oracle Want MySQL

Crystal ball
The Oracle predicts Open Source abundance

In the headlines:

“SAN FRANCISCO–Oracle tried to acquire open-source database maker MySQL, an indication of the profound changes the software giant is willing to make as it adapts to the increasingly significant collaborative programming philosophy.”

Source: CNET

Many questions spring to mind. Among them: are Oracle out of their mind??? They have kept buying Open Source companies ever since that ground-braking statement from Larry Ellion, which called for an Open Source strategy. That recent move probably had many employees sacked, yet it can also be attributed to (or blamed on) a large merger. I personally think it would be interesting to see if Oracle transformed into a new type of company, which heavily relies on Open Source, even more than IBM do.

Oracle databases were lately shown to be poorer in terms of performance when compared against MySQL. Other commercial software fails to keep up with Open Source, so it is one example among several. Will companies like IBM, Red Hat and Novell, who make money out of Open Source, ever become the stalk of a new trend? Is it truly a commercialisation of Open Source, which only Google passionately avoid for the time being? Is it at all acceptable?

Thursday, February 16th, 2006, 2:20 pm

Proprietary Formats and Their Sordid Mess

OPEN formats are based upon a standardised specifications, which ensure global collaboration among applications. Without common formats, hardware are software are simply unable to communicate, unless they come from the same vendor. Formats are also analogous to the notion of a language, or technically speaking, “protocols” and “standards”. They are often agreed upon by an ample panel, which involves industry experts and industry/academy leaders.
What happens, however, when a company goes astray and implements its own formats, which it is unwilling to disclose for competitive reasons? What happens when a format is extended without acceptance by others who already use and depend on it? When common language is violated, disaster is foreseen. An industrial majority (or a monopoly) can use miscommunication as a ‘tool’ which drives competitors away. The temptation to use that tool as a weapon is often there, yet the seminal formats must always be honoured. If not, conversion facilities must be made available, so that a non-lossy route can be followed to ‘sanitise’ the unknown data structures and appendages.

LockI have already complained about proprietary formats that lock one’s personal data. The context in this blog was Palm-powered devices, as well as software packages from Microsoft. It is a terrible scenario when one chooses an appliance or a software package over open formats and is thereafter obliged to use it perpetually. It is an utter lock-in, which has even reached the Web that is openness-motivated. Internet Explorer-only beame more commonplace, yet Firefox has shouted out for a change in recent years.
Let us illustrate the primary contention with the aid of yet another specific example. In question are the advantages of open fromat and exportable data, so let us consider address book (contacts) data on a variety of platforms. I currently hold my address books on Palm’s Address, KDE’s KMail, and Mozilla Thunderbird. Maybe I base my statements on the wrong factors, but experience shows that address confusion and poor organisation skills are prevalent among those that still rely on Microsoft to organise and manage their data. I used to be among those who delegate data organisation to applications (packages) rather than formats. As a consequence, I struggled to move between application, inter-operate or even decipher my own data in the absence of one particular commercial application. Sounds familiar?

In summary, as food for thoughts to ponder: maybe it’s the obscurity of moving data without adherence to standard formats. Maybe it is the lack of import/export utilities and maybe frequent hard-drive re-formatting due to virus attacks and the like. Either way, Linux and Mac users appear to have extensive data which is easily-locatable, inter-changeable, rocoverable and resilient. Openness entails true benefits, which are better understood in the long term.

Thursday, February 16th, 2006, 6:14 am

Search Engines and Benchmark Subjectivity

SEARCHING of the Web is no exact science. If it was, its exhaustive exploration would be infeasible. The more formidable search engines amass information from million of Web sites, each containing huge lumps of information — both textual and media. That information, in turn, could be interpreted and/or indexed in a variety of different forms. Rarely is the content truly understood, which is my personal motivating for knowledge engines.

Mathematics and physics could be argued to be inexact sciences as well, at least when a variety of man-made, non-fundamental fields are introduced. Think of computer science, for example. Its fundamentals assimilate to this complex problem, which is searching the World Wide Web. It is associated with ad-hoc solutions. Computational theories which relate to Turing machines are not tractable enough to make a most correct and efficient algorithm ever crop up and stand out.

Don Knuth has written his popular series of books on the issues of correctness and efficiency in common algorithms. It proves an elegant reference to many computer science practitioners. Problems which are simple, such as element or number sorting, are still handled differently by different algorithms and their efficiency is dependent upon the architecture involved, the scale of the problem, and its nature. Search algorithms likewise, which is why they should be engineered differently depending on a number of key factors. Hence, judgement of the quality of search engines cannot be done objectively, but only ever be estimated using test cases and artificial scoring schemes.

Search buttonStill, everyone wants to discover the perfect recipe to outperforming Google. Others try to reverse-engineer their algorithms and cheat (fame and riches owing to ‘Google juice‘ that is channelled to one’s site/s). Many of us continue favour and recommend Google, which brings the largest number of referrals to most sites in existence. There is a danger here though. Large search engines are the main target for deceit and they are easily confused by spam inasmuch as they are inclined to pick up rare and valuable content.

Quality of search is probably in the mind of the searcher and the result of hearsay — somewhat of a ‘cattle effect’. Even engines that spit out cruft might be defended unconditionally by their innocent users. This may lead the competition to forfeiting the battle and invest fewer resources (e.g. datacentres) in the attempt to catch up. Phrases like “Google it” do not help either as they promote a search monoculture at best.

Related item: Search Engines and Biased Results

Real-time Posts

Posts by @schestowitz

Retrieval statistics: 23 queries taking a total of 0.104 seconds • Please report low bandwidth using the feedback form
Original styles created by Ian Main (all acknowledgements) • PHP scripts and styles later modified by Roy Schestowitz • Help yourself to a GPL'd copy
|— Proudly powered by W o r d P r e s s — based on a heavily-hacked version 1.2.1 (Mingus) installation —|