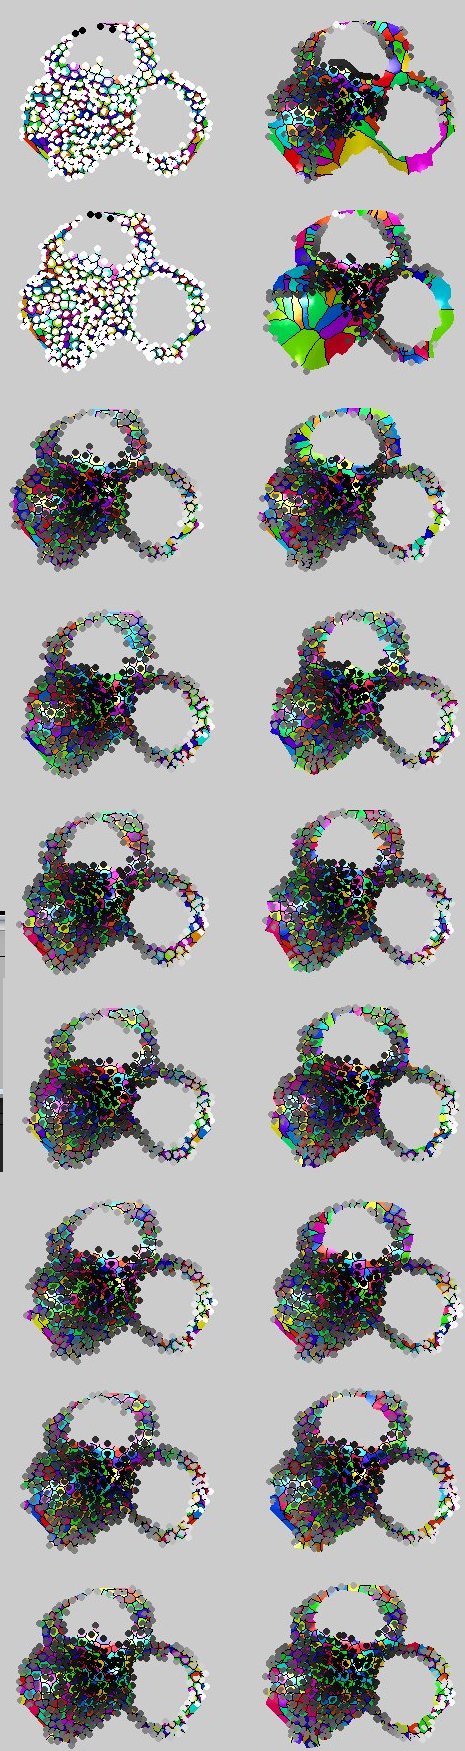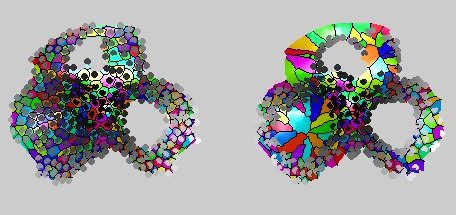Introduction About Site Map

XML
RSS 2 Feed RSS 2 Feed
Navigation

Main Page | Blog Index

Sunday, April 1st, 2012, 3:52 pm

From GMDS/FMM to Canny Edge Detection

Using a more brute force approach which takes into account a broader stochastic process, performance seems to have improved to the point where for 50 pairs (100 images) there are just 2 mistakes using the FMM-based approach and 1 using the triangles counting approach. This seems to have some real potential, even though it is slow for the time being (partly because 4 methods are being tested at the same time, including two GMDS-based approaches).
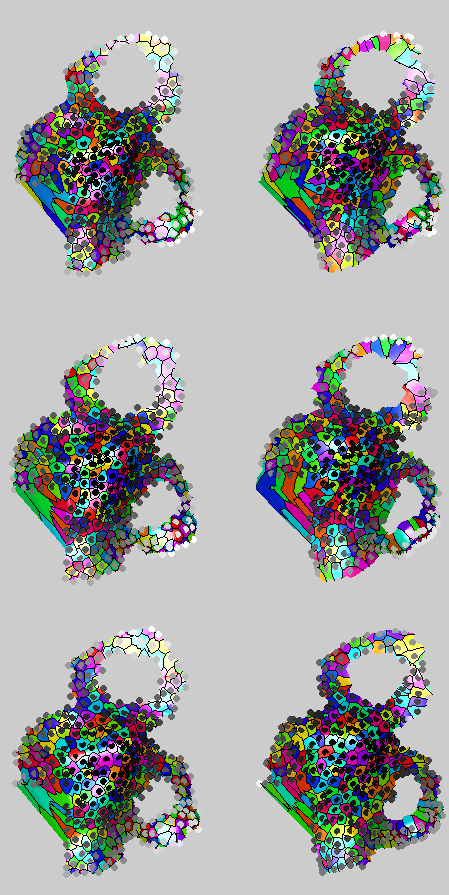
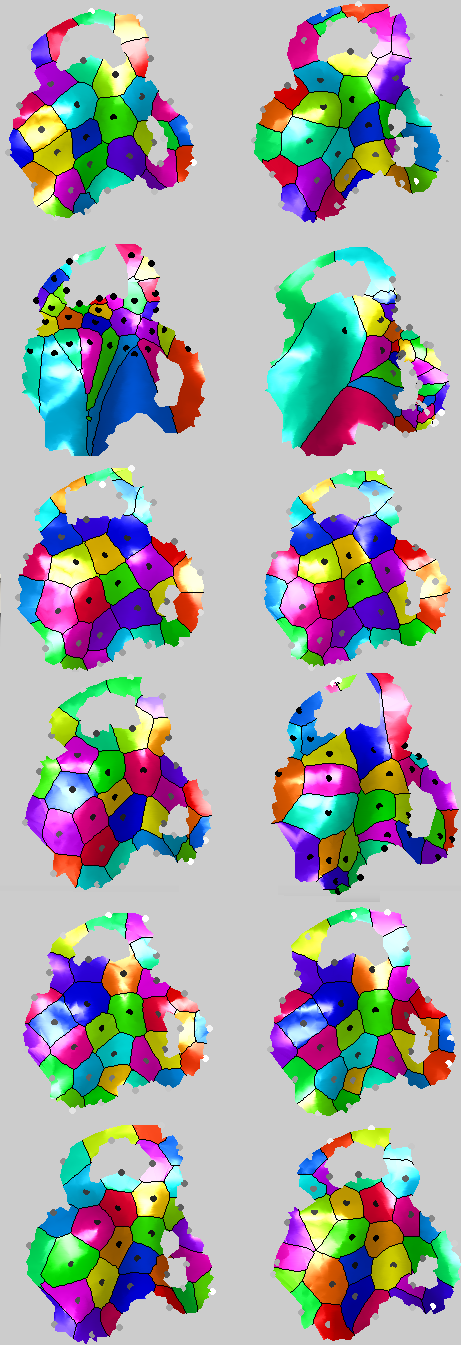
I then restarted the experiment with 4 times more points, 84 images, and I’ll run it for longer. At the start there were no mistakes, but it’s slow. The purpose of this long experiment to see if length of exploration and use of numerous methods at once can yield a better comparator. In the following diagram, red indicates wrong classification. Since similarity is measured in 3 different ways, there is room for classification based on a majority, in which case only one mistake is made. It’s the 9th comparison of the true pairs, which is shown as well. The mouth and arguably whole lower part of the face is a bit twisted; the FMM-based approach got it right, but the other two failed. Previously, when the process was faster, the results were actually better.
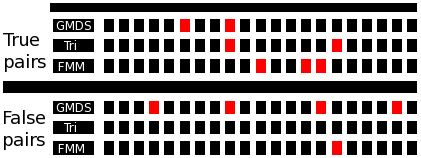
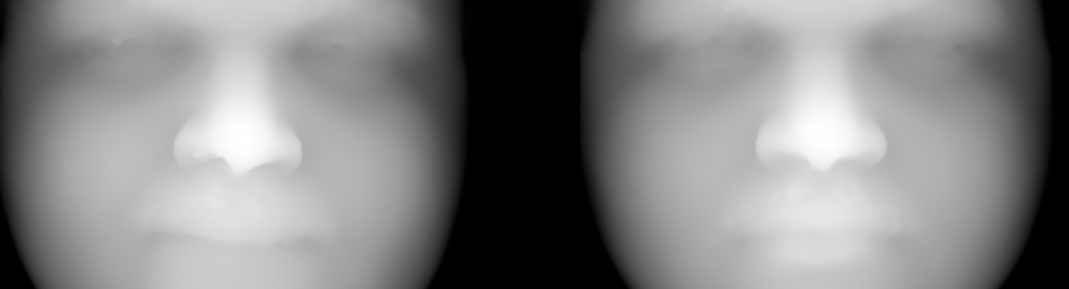
Scatter alternations were made to investigate the potential of yet more brute force. I reran the experiments as before but with different parameters that scatter the random sample closer to the centre of the face and this eliminated the one mistake made before (9th true pairs). The changes resulted in one single result which was not correct: the 15th image in the other gallery. Whereas it was previously intuitive to find a fix for one mistake. when this fix introduces a mistake elsewhere it’s time to think of an approach change. One solution might be to increase the scatter sample/range, but it is already very slow as it is.
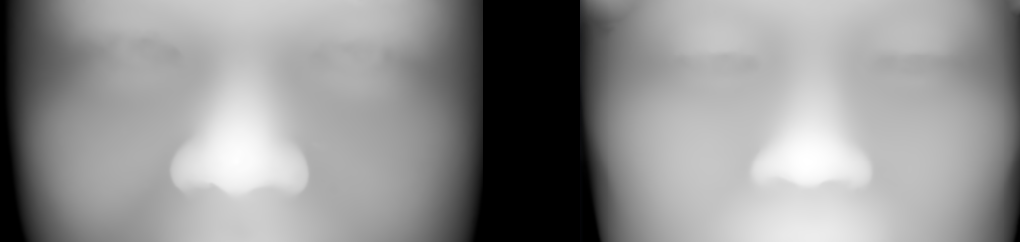
Edge detection was then explored as another classifier facilitator.

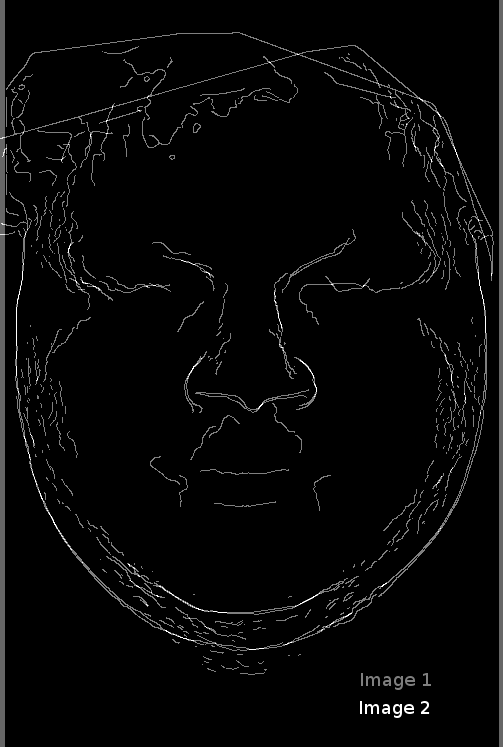
In order to address the recurring issue where misclassifications are caused by improper account for details versus topology, another approach is going to be implemented and added to the stack of methods already in use. The approach will use edge detection near anatomically distinct features and then perform measurements based on the output. As the image below shows, GMDS is still inclined to accept false pairs as though they are matching sometimes and this weakens the GMDS “best fit” approach.
I have implemented a 3-D classification method based on filters and Canny edge detector, essentially measuring distances on the surface — distances between edges. So far, based on 20 or so comparisons, there are no errors. But ultimately, this can be used as one classifier among several.
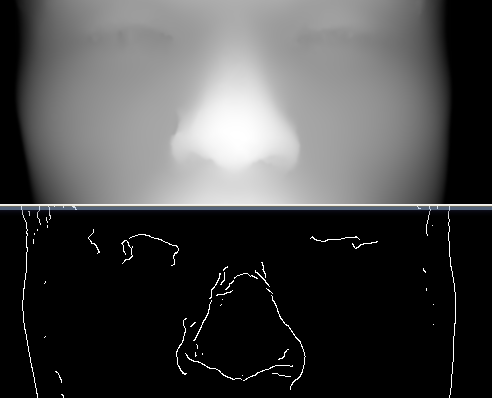
The thing is about Canny is, if we do that, we might as try using the set

Laplacian(I) - g(I)*div(g(I)/|g(I)|) = 0

where g(I) = grad (I) which is the Haralick part of the “Canny” edge detector, i.e. without the hysteresis integration.

I decided to look into changing it. Currently I use:

    % Magic numbers
    PercentOfPixelsNotEdges = .7; % Used for selecting thresholds
    ThresholdRatio = .4;          % Low thresh is this fraction of the high.
    
    % Calculate gradients using a derivative of Gaussian filter 
    [dx, dy] = smoothGradient(a, sigma);
    
    % Calculate Magnitude of Gradient
    magGrad = hypot(dx, dy);
    
    % Normalize for threshold selection
    magmax = max(magGrad(:));
    if magmax > 0
        magGrad = magGrad / magmax;
    end
    
    % Determine Hysteresis Thresholds
    [lowThresh, highThresh] = selectThresholds(thresh, magGrad, PercentOfPixelsNotEdges, ThresholdRatio, mfilename);
    
    % Perform Non-Maximum Suppression Thining and Hysteresis Thresholding of Edge
    % Strength
    e = thinAndThreshold(e, dx, dy, magGrad, lowThresh, highThresh);
    thresh = [lowThresh highThresh];

There is a lot that we can do with edges to complement the FMM-based classifiers (triangles count, GMDS, others), but moreover, I am thinking of placing markers on edges/corners (derived from range images) and then calculating geodesics between those. Right now it is all Euclidean, without account for spatial properties like curves in the vicinity. By choosing many points and repeating the process everything slows down, but previous experiments show this to bear potential. None of it is multi-scale just yet.

What we do with the edges is also risky, as the edges strongly depend on the pose estimation and expression. In pose-corrected pairs (post-ICP) I measure distances between face edges and nose edges. Other parts are too blurry and don’t give sharp enough an edge which is also resistant to expression. The nose is also surrounded by a rigid surface (pose-agnostic for the most part).

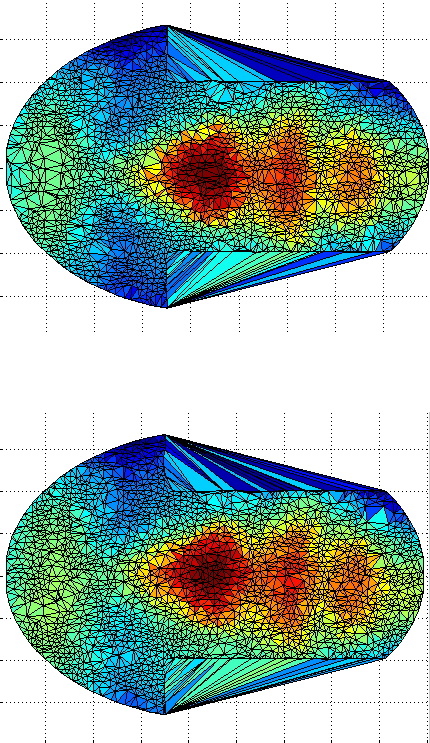
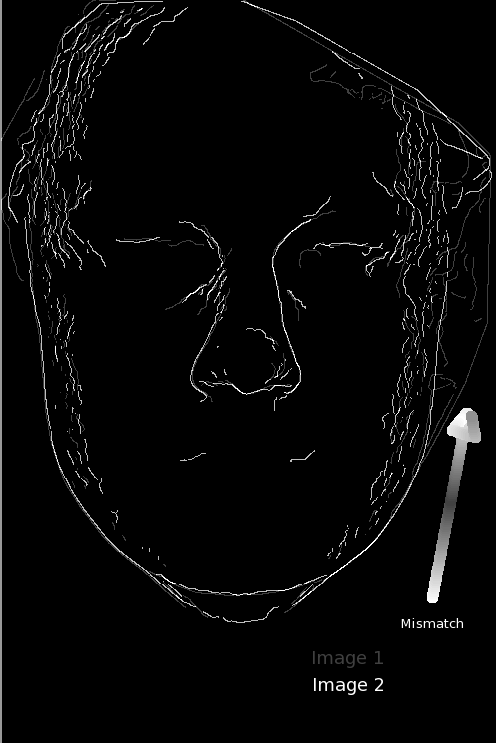
Problematic cases still exist nonetheless and I am trying to find ways to get past them. There are clearly problematic cases, such as this first occurrence in the 25th pair, where edge detection is not being consistent enough to make these distances unambiguous. In such cases, Euclidean measures — just like their geodesic counterparts — are likely to fail, incorrectly claiming the noses to be of different people.
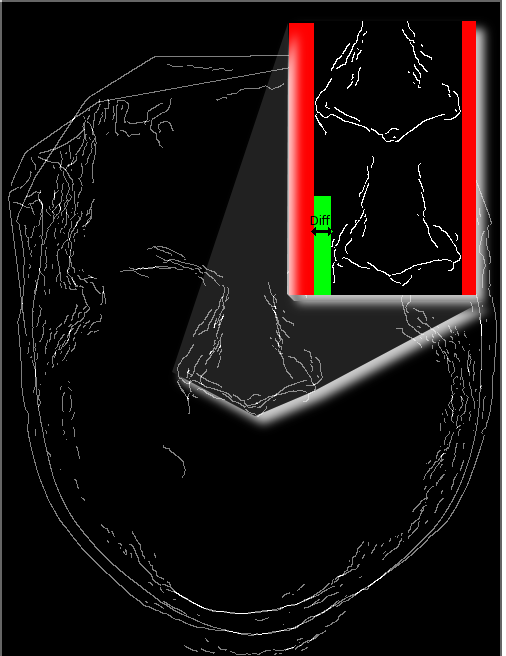
A modified edge detection-based mechanism is now in place so as to serve as another classifier. It does fail as a classifier when edge detection fails, as shown in the image.
Friday, March 23rd, 2012, 5:37 pm

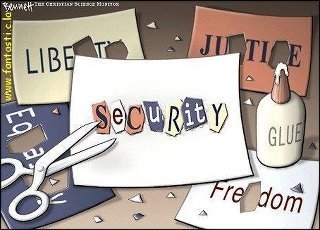
How ‘Security’ Works

Security

Thursday, March 22nd, 2012, 11:36 pm

Random Positions in GMDS- and FFM-based Analysis

The latest batch of experiments looked at how one might cope with a mask closer than usual to the eye’s centre. I used harder pairs.

It did not work too well. One remaining limitation is that in an attempt to determine fiducial-esque points based on unmarked (not annotated) 3-D data there is little other than the nose tip that can consistently and accurately be pinned down. The eyes in particular are not simple to segment in 3-D — not without some help from 2-D anyway — mostly because the corners are fuzzy in 3-D. While slight head rotations can be annulled with ICP, there is still a difficulty associated with true distances as measured based on the range images. Accurately-measured geodesic distances are supposed to be robust to that, but in practice when there is slight rotation difference some of the calculations don’t add up. The sensitivity to inherent differences is often outweighed by pose.

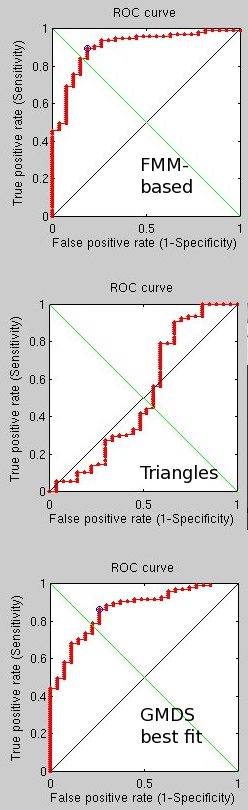
Classification mistakes were partly caused by hair, occlusion, and other factors. I have rerun the same experiments as before with twice the number of vertices, but unsurprisingly, the results were about the same. The excessive detail gains never brought much improvement in terms of verification performance. Next, I took the best approach of the bunch and ran it on some of the hardest cases. The ROC curve is shown while for simpler cases the experiment is still being run on two servers.

There’s still no hope of beating state-of-the-art performance levels, unless of course a significantly improved variant is found.

Some of the problems are easier for the human eye to see, such as cases where hair penalises the scoring mechanism, as shown in the picture below.

Random points were then attempted, adding a stochastic nature to this problem. In order to make GMDS ‘fail’ most badly only in the case of false pairs, I have tested some new masks and measured verification performance reached by using them. For GMDS it failed quite badly, but with the other FMM-based approach — applied to some hard cases — I got the results shown in the ROC curve. Rather than dilating the masks and varying the hole sizes I would like to try varying positions from which to dilate in order to sample more distinct regions and measure distances upon those. This seems like an approach with real potential, provided the random (or fixed) sample of points is large enough to compensate for noise/intra-person variation. The latest experiment was preparatory towards this approach.

Random positions were further tested by making a variation, an improvement to the above. By letting the anchor points move around a bit (randomly within range) I was unable to get better performance than before (just over 90% verification rate on hard cases too). There are other methods that I could try next…

120 random positions were then placed on pairs to further test the approach. These further attempts to improve performance by moving points randomly (and this time taking a larger random sample) were not quite so successful. The general premise was, by taking many points around the face and expanding from them (with geodesic means) will lead to a good and rather unique signature. In practice, however, the measure is insensitive to real anatomical differences. Intra-person differences can outweigh inter-person differences. I’ll try another approach, but it will take days for results to arrive.

Although this is being tested on faces at the moment, the methods are generalisable and can be applied to any biomedical data for similar purposes.

Friday, March 16th, 2012, 12:07 am

Using a Phone Anonymously in the UK

Wall

THOSE WHO KNOW history will appreciate the importance of civil rights. Those who saw the Berlin Wall built will possibly recall all that was learned about the Stasi for example.

In this age of crackdown on journalism and on civil liberties in the UK (simply censorship and gagging) we ought to be aware of the power of those who run the country. They are very rich people. The surveillance gives them more power. While CCTV is impossible to dodge, phones are not obligatory for most people. Phones are surveillance devices, but phones has other features, calls included. Those entice people into carrying tracking devices (walking along with them) and always leaving those switched on, with an identity attached to them (just like a landline). There are other problems with mobile phones.

I have several mobile numbers and phones, but they do not come with tracking per se, as with pay as you go (PAYG) in the UK it turns out that it is possible — albeit hard — to purchase and use a phone anonymously (unless someone works hard to decipher the identity). Here is what I found in each major shop:

Carphone Warehouse: always must disclose personal details, no matter the network, phone, plan, and payment method

Orange: must give personal details to the cashiers

Vodafone: needn’t give personal details, can pay with cash

Phone4U: need to pay more for anonymous usage

Virgin: can avoid giving personal details, but there are caveats

To the credit of all the above, no store had people working for it who give a ‘funny’ or ‘dirty’ look when asked about privacy implications, maybe because I don’t look like a terrorist or maybe because I’m exceedingly polite and smile all the time. Either way, it is not as bad as it could be. To ask for privacy these days is almost like confessing to doing something malicious.

Wednesday, March 14th, 2012, 10:23 pm

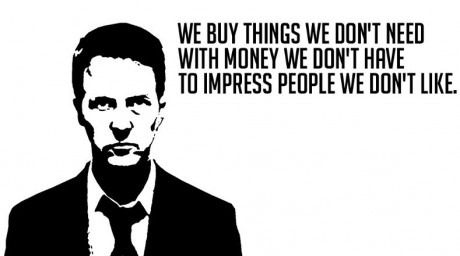
Consumerism – When One Does Not ‘Get’ Life

Quote

Monday, March 12th, 2012, 3:37 pm

UK Censorship

WAR CRIMES are considered a lot less serious than whistle-blowing, according to UK standards. The government is currently trying to suppress the publication of stuff that should have been public all along. It is very sad to see that once again — as expected — much of the public will neither know nor care. And why? Because “censorship” is perceived as bad only as long as “they” do it, not “us”. A lot of people are brainwashed into the mindset that our own censorship is “defending” us and others’ is “suppressing” them.

Richard Stallman got it right about censorship. All censorship is bad. If we go down the slippery slope of selective and hypocritical censorship but never stand up, we deserve the consequences.

Monday, March 12th, 2012, 3:30 pm

Topological Mistakes in GMDS

In particular cases, GMDS failures (topological mistakes) continue to be a problem, but it is possible to detect whether that happens and then just filter those cases away. Having run experiments that try to overcome these occasional failures, I got nearly flawless classification with the FMM-based methods when it’s applied to simpler pairs, less successful when dealing with harder cases (an order of magnitude more failures, as shown in the ROC curve).
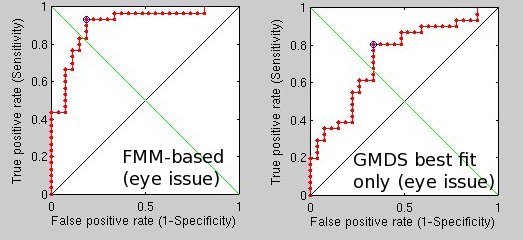
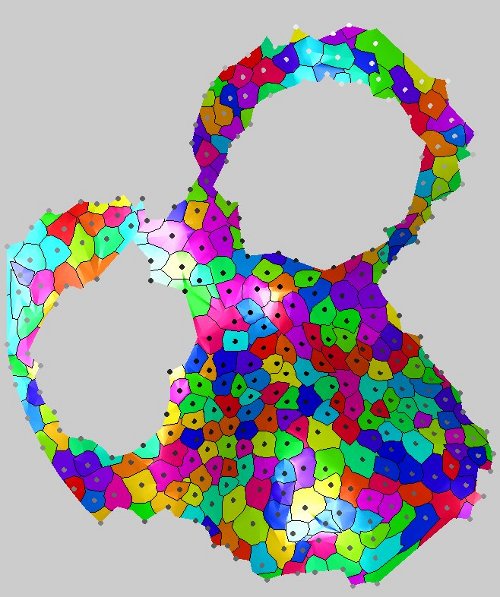
In order to reduce the recurrence of failures I am varying the size of the holes and the overall surface area, noting that still, even for corresponding surfaces, there are sometimes cases of GMDS failure.

More ROC curves were learned thereafter. Dealing yet again with cases that are hard, the following results were obtained by making further changes to the masks, even though ongoing experiments look at a wider range of attempts, over which a best fit or average get taken. By mixing the more successful approaches, better rates can be assured. By adding the simpler pairs, better rates can also be assured.

Real-time Posts

Posts by @schestowitz

Retrieval statistics: 23 queries taking a total of 0.106 seconds • Please report low bandwidth using the feedback form
Original styles created by Ian Main (all acknowledgements) • PHP scripts and styles later modified by Roy Schestowitz • Help yourself to a GPL'd copy
|— Proudly powered by W o r d P r e s s — based on a heavily-hacked version 1.2.1 (Mingus) installation —|